NVIDIA H200 NVL PCIe GPU Enterprise Guide
NVIDIA H200 NVL PCIe GPU: Revolutionizing Generative AI and Large Language Model Compute Footprints
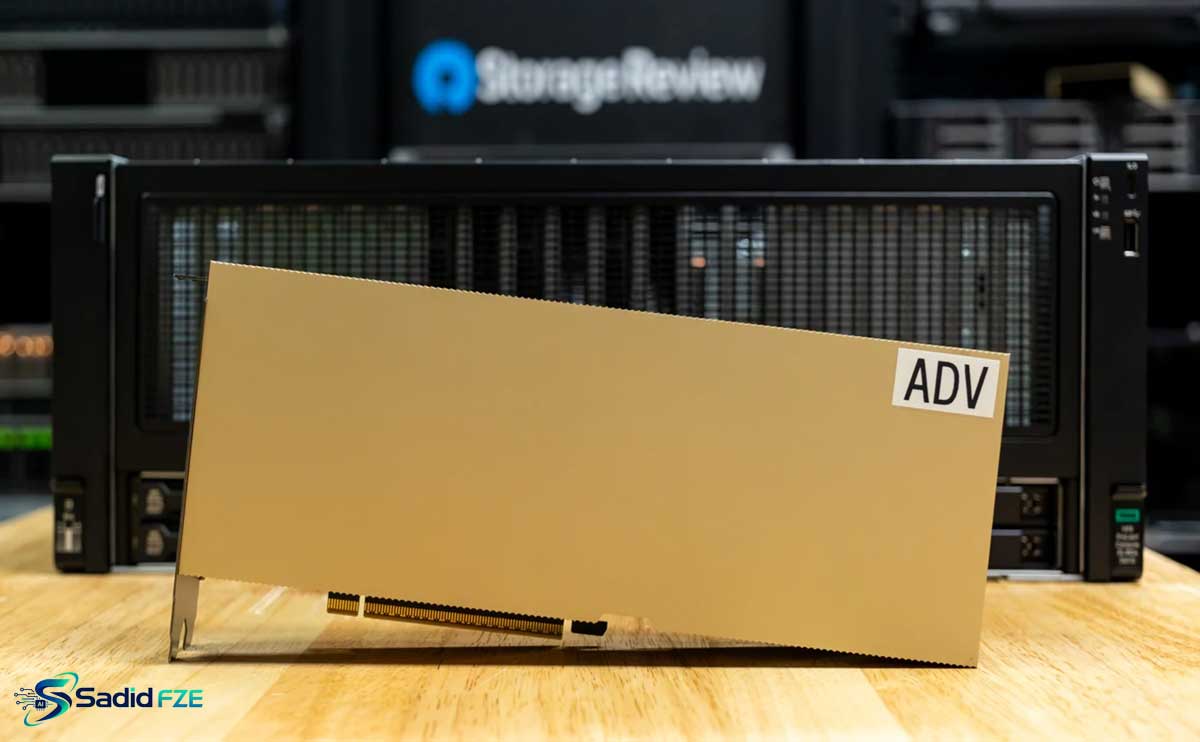
The global proliferation of generative artificial intelligence, multi-modal foundation models, high-throughput large language model (LLM) inference, and complex scientific computational modeling has reshaped the requirements of modern data centers. As enterprises transition from basic model training to serving millions of concurrent real-time inference queries, memory bandwidth and memory capacity have emerged as the single most critical performance bottleneck. The NVIDIA H200 NVL PCIe GPU represents the pinnacle of enterprise data center hardware acceleration, combining NVIDIA’s industry-defining Hopper micro-architecture with ultra-fast HBM3e high-bandwidth memory within a standard PCIe form factor.
Procured and distributed internationally by SADID FZE—operating from Dubai’s premier Jebel Ali Free Zone (JAFZA), UAE—the NVIDIA H200 NVL PCIe GPU allows data center operators, enterprise cloud providers, sovereign AI initiatives, and research institutes to seamlessly deploy next-generation computational nodes within existing rack topologies. This comprehensive guide evaluates the micro-architecture, memory breakthroughs, financial ROI, and strategic B2B supply channels for the NVIDIA H200 NVL PCIe accelerator.
1. Hopper Architecture and HBM3e Memory Engineering
Built upon the proven foundation of the NVIDIA Hopper architecture, the H200 NVL introduces major enhancements designed specifically to conquer memory-bound AI workloads. While traditional GPUs are often limited by how quickly data can move from VRAM to processing cores, the integration of ultra-fast HBM3e memory unlocks unprecedented terabyte-per-second memory bandwidth speeds.
Core Hardware Specifications & Innovations:
- Architectural Foundation: Powered by the NVIDIA Hopper GPU micro-architecture with integrated Transformer Engine hardware acceleration.
- Breakthrough HBM3e Memory: Equipped with massive HBM3e high-bandwidth memory delivering multi-terabyte-per-second memory bandwidth to prevent memory starvation during massive LLM token generation.
- PCIe Express Form Factor: Dual-slot enterprise PCIe design allowing universal compatibility with standard 2U and 4U OEM rackmount server configurations.
- NVLink Bridge Connectivity: Supports high-speed dual-GPU NVLink bridge interconnects, allowing adjacent PCIe GPUs to share memory pools and function as a single high-capacity compute node.
- Hardware Confidential Computing: Built-in zero-trust cryptographic security engines that protect sensitive proprietary AI models and confidential enterprise datasets in memory during execution.
- Precision Support: Full mathematical precision range, including FP8, FP16, BF16, INT8, and TF32 format handling for both deep learning training and high-density inference.
By implementing HBM3e memory within a standard PCIe interface, the H200 NVL provides up to 1.4x to 1.9x higher memory throughput compared to predecessor architectures. This allows enterprises to serve multi-billion parameter AI models directly from single-node server chassis without needing complex, customized board modifications.
2. Primary Enterprise Workloads and Data Center Deployment
The NVIDIA H200 NVL PCIe GPU is tailored for high-volume commercial enterprises and cloud platform operators hosting mission-critical AI pipelines.
A. High-Throughput Large Language Model (LLM) Inference
Commercial LLM services demand sub-second token delivery for millions of concurrent user sessions. The massive HBM3e memory bandwidth of the H200 NVL allows massive parameter models (such as Llama 3 70B/405B or GPT-class models) to execute inference with larger batch sizes, drastically increasing queries served per minute per server rack.
B. Generative AI & Multi-Modal Foundation Model Serving
Multi-modal AI pipelines that combine text, vision, audio, and video processing require instantaneous data ingestion and large memory buffers. The H200 NVL handles multi-modal model parameters natively, eliminating model-offloading delays during high-density API calls.
C. Scientific Research, Molecular Modeling & Genomics
National laboratories, pharmaceutical researchers, and climate research centers utilize high-performance computing (HPC) clusters to model molecular dynamics, execute genomic sequencing, and run weather prediction models. The double-precision FP64 performance of the H200 NVL speeds up complex scientific simulation algorithms.
D. Sovereign AI & Confidential Enterprise Cloud Hosting
Governments, healthcare institutions, and financial organizations require absolute zero-trust data security when deploying AI infrastructure. Hardware-based Confidential Computing built into the Hopper architecture encrypts data in-flight and at-rest within memory, satisfying strict international data protection mandates.
3. Commercial Advantages and Financial Return on Investment (ROI)
Investing in enterprise-class data center hardware through SADID FZE empowers IT executives to optimize capital expenditures (CapEx) while maximizing revenue generation potential per server rack.
1. Dramatic Reduction in Cost-Per-Inference API Call
For cloud providers and commercial AI platforms, hardware profitability depends on minimizing electricity and rack space costs per served query. By increasing token generation speed and batch density via HBM3e memory, the H200 NVL significantly lowers the operational cost per inference API call.
2. Seamless Integration into Existing Server Infrastructure
Custom form-factor accelerators often require proprietary chassis designs and expensive liquid cooling manifold replacements. The standard PCIe form factor of the H200 NVL allows data center operators to drop cards directly into standard air-cooled or hybrid-cooled OEM server racks, minimizing deployment capital outlay.
3. Accelerated Time-to-Revenue for Cloud Service Providers
Data center capacity shortages make compute footprint efficiency paramount. Deploying higher-density H200 NVL nodes allows cloud service providers to offer high-demand GPU cloud instances to enterprise clients faster, accelerating time-to-revenue.
4. Hardware Performance Matrix
The operational matrix below illustrates the performance advancements achieved when deploying the NVIDIA H200 NVL PCIe GPU across enterprise server environments:
| Operational Attribute | Standard Enterprise PCIe GPU | NVIDIA H100 PCIe Accelerator | NVIDIA H200 NVL PCIe GPU |
|---|---|---|---|
| Memory Technology | GDDR6 / Standard VRAM | HBM2e / HBM3 Memory | Ultra-Fast Next-Gen HBM3e Memory |
| LLM Inference Token Throughput | Baseline Performance | High Throughput | Maximum Multi-Terabyte Throughput (up to 1.9x boost) |
| Form Factor Flexibility | Standard PCIe Slot | PCIe / SXM Options | Universal Enterprise Dual-Slot PCIe |
| Data Security Architecture | Software Encryption | Confidential Computing Ready | Full Hardware-Enforced Confidential Computing |
| Primary Deployment Scope | Basic Workstations / Compute Nodes | General AI & HPC Clusters | Flagship LLM Inference, Generative AI & Sovereign Cloud |
5. International B2B Supply and Procurement via SADID FZE
Procuring flagship data center GPU hardware requires reliable supply partners capable of handling complex international trade regulations and high-volume logistics. Operating from Dubai’s world-renowned Jebel Ali Free Zone (JAFZA), UAE, SADID FZE provides premier B2B technology distribution services to global corporate accounts, system integrators, and government technology initiatives.
When you procure the NVIDIA H200 NVL PCIe GPU through SADID FZE, you receive guaranteed original hardware authentication, full global trade export compliance management, structured corporate billing, and swift international freight delivery tailored for enterprise IT projects.
6. Technical References and Official Resources
- NVIDIA H200 NVL Enterprise Accelerator Technical Specifications: https://www.nvidia.com/en-us/data-center/h200/
- NVIDIA Hopper Architecture Architecture & Deep Learning Whitepaper: https://www.nvidia.com/en-us/data-center/hopper-gpu-architecture/
- JEDEC HBM3e High-Bandwidth Memory Standards: https://www.jedec.org/